







AI is already changing malware analysis, but Cisco Talos’ latest research highlights the part defenders need to design around: attackers are beginning to target the analysis pipeline itself.
In new research from Cisco Talos, malware authors are embedding natural-language instructions inside samples in an attempt to influence automated AI-assisted triage. The code still behaves like malware. The added text is aimed at the tool or model reading extracted strings during analysis.
That makes this less of a “killer AI evasion” story and more of a process-control story. If your security workflow feeds file contents, script comments, strings, logs, or decompiled output into an AI system, the pipeline needs strict boundaries between analyst instruction and adversary-controlled evidence.
What Talos reported
Talos tracks this behavior as AI-analysis evasion: malware that contains text intended to manipulate an AI-assisted analysis layer. The research traces this across several malware families, including examples where simple comments or string templates attempt to convince an analysis model that a script is benign, copyrighted, off-limits, or otherwise not worth reverse engineering.
The important detail is that the technique does not change the malware’s runtime behavior. It is not packing, encryption, anti-debugging, or virtual-machine detection. It is social engineering aimed at an automated reviewer.
Talos also found that these instructions are cheap for attackers to add and can sometimes steer results, but they come with a major weakness: the evasion content has to be present as readable text. That gives defenders a detection surface.
Why this matters for SMBs and government contractors
AI-assisted security tooling is becoming normal, including for smaller teams. Managed detection providers, EDR platforms, sandboxes, SIEM copilots, malware triage scripts, ticket summarizers, and analyst workbenches may all use language models somewhere in the workflow.
That creates a new trust question. If a tool summarizes a suspicious PowerShell script, email attachment, JavaScript file, crash dump, or malware string table, does it treat the content as hostile evidence? Or can text inside the artifact influence the model’s instructions?
For government contractors, this is especially relevant because AI-assisted triage may be used to speed incident response, vulnerability review, software assurance, or supplier-risk workflows. A bad summary can slow escalation, misclassify evidence, or bury an indicator that should have triggered containment.
The defensive lesson: evidence is not instruction
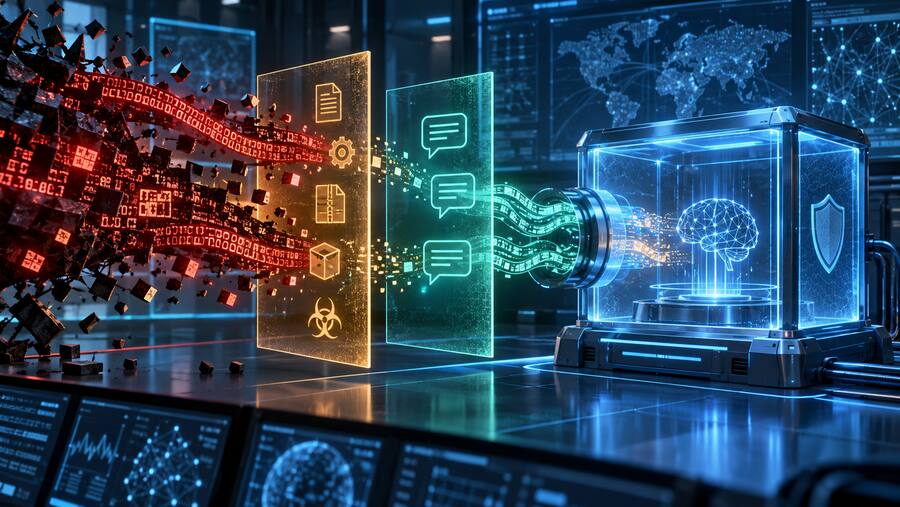
The core control is simple: anything extracted from a sample must be handled as untrusted data. A model should never be allowed to treat malware strings, comments, decoded payloads, document text, or attacker-controlled metadata as instructions.
That means AI security workflows need the same separation-of-trust mindset defenders already apply to web apps, scripts, and logs. User prompts, system instructions, retrieved evidence, and analysis outputs should be clearly separated in the pipeline.
Practical controls to implement
- Separate instructions from evidence. Keep analyst/system prompts isolated from extracted sample content. Wrap artifacts as quoted evidence, not executable or authoritative text.
- Detect suspicious analyzer-directed language. Hunt for strings that address AI systems, scanners, reverse engineers, sandboxes, copyright refusal logic, legal threats, or “do not analyze” claims inside binaries and scripts.
- Require deterministic checks before AI summaries. Hash reputation, static signatures, YARA, sandbox behavior, network indicators, process behavior, and file metadata should not be overridden by a model’s natural-language conclusion.
- Log model inputs and outputs for review. If an AI assistant downgrades a suspicious file, analysts should be able to see what artifact text was provided and whether it contained prompt-injection attempts.
- Use confidence gates. AI triage should assist analysts, not silently close incidents. Low-confidence or contradiction-heavy summaries should escalate, not suppress alerts.
- Test your own tools. Seed safe internal samples with obvious prompt-injection strings and verify that sandboxes, copilots, ticket summarizers, and malware-analysis helpers continue to classify based on behavior and evidence.
What to hunt for now
Defenders can start with straightforward detections. Search malware repositories, EDR telemetry, sandbox artifacts, and script logs for phrases that directly address “AI,” “LLM,” “assistant,” “analysis,” “reverse engineering,” “copyright,” “system prompt,” or “do not analyze.” The goal is not to catch every variant. The goal is to identify artifacts attempting to influence the analysis layer.
Teams should also review any workflow that automatically summarizes unknown files, phishing kits, scripts, browser extensions, package contents, or memory strings. If the workflow sends attacker-controlled content to a model, it should include explicit guardrails and downstream validation.
Bulwark Black assessment
This is an early warning, not a reason to abandon AI-assisted security. The conventional detection stack still matters. Sandboxes, static analysis, behavioral telemetry, signatures, and analyst judgment are not defeated because a malware author added a persuasive comment.
But the trend does show that attackers understand where defenders are headed. As AI becomes part of malware triage and incident response, adversaries will test the seams between data and instruction. The organizations that benefit from AI safely will be the ones that engineer those seams deliberately.
For SMBs and government contractors, the practical move is to treat AI analysis tools like any other security-critical automation: constrain inputs, verify outputs, log decisions, and never let untrusted artifact text become an instruction.